A few more words on human error: an illustrative example

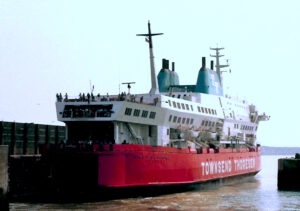
On the evening of 6 March 1987, the Herald of Free Enterprise, one of three Spirit-class ferries operated by Townsend Thoresen, left Zeebrugge fully loaded and bound for Dover. Just over twenty minutes later, shortly after passing the harbour’s outer mole, she capsized, eventually claiming the lives of 193 passengers and crew.

The immediate cause could hardly have been more prosaic—or more merciless. The crew had failed to close the enormous bow doors through which vehicles entered and left the car deck. Once the ship cleared the harbour and began gaining speed, vast quantities of water poured onto the deck. Within minutes, the ferry was lying on her side. Only the shallow water and a fortunate sandbank prevented her from disappearing completely beneath the surface.

There was little dispute about the immediate cause: the bow doors had been left open. Identifying who was responsible, however, turned out to be a much more complicated exercise—one that would ultimately lead to important changes in maritime safety and, more broadly, to the way human error is understood.

The first suspect appeared rather quickly.

Closing the bow doors before departure was the responsibility of the assistant bosun, Mark Stanley. Shortly before sailing, Stanley went down to his cabin for a short break. He fell asleep and was still asleep when the ship dropped her moorings.

So the investigation was clearly dealing with human error, and the human in question seemed obvious: Stanley had overslept an important duty.

Case closed?

Happily, the investigators did not stop there.

They discovered that this was not the first time something remarkably similar had happened. In 1983, another ferry belonging to the same company—the Pride of Free Enterprise—had sailed with its doors open after another assistant bosun had fallen asleep. On that occasion the mistake was noticed in time and disaster was avoided. There had, in fact, been several previous occasions on which company vessels had gone to sea with bow or stern doors open.

At that point, blaming one sleepy junior crew member began to look less satisfactory. Passenger ferries should not be capable of sinking simply because one tired person fails to wake up at the right moment.

There is another detail worth remembering about Stanley. After the capsize, despite being injured, he returned to help rescue passengers trapped inside the vessel until cold and blood loss forced him to stop. The man whose mistake helped trigger the disaster was also capable, minutes later, of considerable courage.

Human beings are inconveniently complicated like that.

So the investigation moved one step further up the chain of command, to Stanley’s superior: Chief Officer Leslie Sabel.

Sabel had responsibility for ensuring that the bow doors were closed. He had been on the vehicle deck, but left shortly before departure without actually seeing them shut.

Surely that qualified as serious negligence and a clear failure of duty?

It did. But again, the answer was not quite complete.

Another set of company instructions could require the same officer to be on the bridge before departure while his loading duties still kept him on the vehicle deck. The inquiry itself recognised that this created a conflict between his responsibilities. At the same time, officers were under considerable pressure to get the ferries away promptly once loading was finished.

Most of the time, of course, everything worked. The officer left the deck, somebody closed the doors, and the ship sailed safely. Nothing terrible happened.

And repetition has a remarkable ability to make an unsafe practice feel perfectly normal.

So responsibility moved another step upwards.

The captain was ultimately responsible for the safe departure of the vessel. Surely it was his duty to recognise the dangerous situation and stop the ship before it left harbour.

Sadly, not this time.

The captain could not see the bow doors from the bridge. Nor was there any indicator or other visual cue telling him whether they were open or closed.

There was something else too.

Townsend Thoresen’s standing orders effectively operated on a system of negative reporting: if nobody reported a deficiency, the Master could assume that the vessel was ready for sea.

And that was exactly what he did.

The inquiry still found the captain negligent. But it also noted that other masters were using essentially the same defective system, and that previous incidents involving open doors had not been communicated adequately to them.

So the investigation moved further again—to the people who had designed and managed that system.

Why should a safety-critical operation rely on the principle that “no news means everything is safe”? Why wasn’t there a simple “DOOR OPEN” light on the bridge? The problem hardly called for cutting-edge technology.

And why had no effective lesson been learned from earlier incidents?

The lessons certainly had opportunities to be learned.

As early as 1985, one of the company’s captains had specifically proposed fitting indicator lights on the bridge so that officers could see whether the bow doors were closed. The suggestion was circulated within management, but dismissed. One response even questioned whether an indicator was really necessary when someone was already being paid to close the doors.

The inquiry later concluded that, had the proposal received proper consideration, the disaster might well have been prevented.

By now, the picture looked very different from the one we started with.

Stanley had made a mistake. Sabel had failed in his responsibilities. The captain had departed without knowing for certain that the vessel was secured. Procedures had allowed conflicting duties and unsafe assumptions to become routine. Management had received warning signs and opportunities for improvement but had failed to act on them.

None of those discoveries made the previous failures disappear. They simply showed that stopping at any one of them would have produced an incomplete explanation.

The official inquiry ultimately reached much the same conclusion. Having examined the actions of the crew, it found itself led inexorably further up the organisation, eventually describing the company as suffering, “from top to bottom”, from a “disease of sloppiness”.

The subsequent criminal proceedings revealed another interesting problem.

Company managers were prosecuted for gross negligence manslaughter, and the operating company itself was charged with corporate manslaughter. The prosecution ultimately failed. At the time, English law struggled to deal with exactly this kind of distributed organisational responsibility: to convict a company, the prosecution effectively needed to identify a sufficiently senior individual whose personal gross negligence could be treated as the negligence of the company itself.

The evidence pointed towards failures spread throughout an organisation, while the law was still searching for one sufficiently important human being to pin them on.

The Herald of Free Enterprise teaches many lessons, but perhaps one of the most important is about the way we think about human fallibility.

Human beings make mistakes. We become tired. We lose concentration. We overlook things, make poor judgements, misunderstand instructions and occasionally behave negligently. These weaknesses are as inseparable from us as the better aspects of human nature—kindness, courage, compassion, self-sacrifice and love.

Accepting our fallibility, studying it and designing the way we live and work around it will take us towards a safer world far more effectively than treating every mistake as an opportunity for blame or humiliation.

That does not mean removing personal responsibility. Stanley was responsible for failing to close the doors. Sabel was responsible for leaving without ensuring that they were closed. The captain carried his own responsibility, and management carried theirs.

Understanding why somebody made a mistake does not make the mistake disappear.

But neither should identifying one mistake bring the investigation to an end.

Thanks to investigators who resisted the temptation to stop when they reached an easy answer—and then resisted it again when they reached the next one—the Herald of Free Enterprise became an important case in the development of maritime safety and in our understanding of organisational failure.

Would any of that have happened if the inquiry had assigned one hundred percent of the blame to the sleeping assistant bosun?
A few words on human error

It is widely assumed that between 70% and 90% of serious accidents across all industries can be attributed to human error. While this is probably about right—you can’t argue with statistics—few people understand what kind of error lies behind that incredible number.

Upon hearing the words ‘human error’, most people think of the person or people directly involved in the accident—the ‘operator’. Was it a road traffic collision? Probably the driver who misjudged the situation. An aeroplane crash? The pilot pulled too hard on the controls. An explosion at a power plant? Must have been some young and clumsy shift operator.

While any of these may, of course, be the case, reality is rarely that straightforward. Many industries—particularly high-risk ones such as aviation, traffic management, construction and nuclear energy—have long been interested in reducing their accident rates. They have worked hard to introduce safety controls that reduce the chance of human error, or at least make its consequences more manageable. Did you know, for example, that the white swirl painted on an aircraft engine is not just a funny bit of styling, but is there to help ground crews see that the engine is running when they may not be able to hear it at a busy airport?

Those efforts have paid off. Commercial aviation, for example, has become one of the safest methods of transport available to human beings, with air travel around 170 times safer per mile than travelling by car, and orders of magnitude safer than walking. In 2023, the industry could boast zero fatalities, despite air traffic reaching a record-breaking 32 million flights.

This increase in safety has had a curious side effect, though. While the proportion of accidents attributed to human error has remained somewhere around that 70–90% mark—of a much smaller number of accidents—the source of human error has propagated well up the chain of command.

A modern human error, particularly in a high-risk industry, is rarely just an operator error. Everything possible has been done to reduce the chances of basic ‘human fallibility’ errors. Most of the improvement in safety records has been achieved not by carefully selecting only responsible, prudent, well-disciplined and positive people for safety-critical positions (there are only so many of us 😉), but by designing systems in such a way that their susceptibility to human fallibility is low—and their tolerance of it is high.

It is highly unlikely that a poorly qualified, exhausted or drunk pilot will make it into the cockpit—and even if one somehow does, there is another qualified pilot sitting right beside them. It is next to impossible for an unqualified person to enter the control room of a nuclear power plant, just as it is impossible to gain that qualification without rigorous training and having your knowledge verified by a diligent examiner. Critical jobs are rarely assigned to a single person without some form of supervision, checking or independent control.

Today, traditional operator failings—fatigue, drink-driving, lack of discipline, negligence, poor training and the like—rarely become the sole root cause of a high-severity accident. Multiple things usually have to go wrong at the same time.

More importantly, alongside increased attention to system resilience, there has also been a qualitative shift in the way we think about human behaviour and workplace failures. Gone are the days of imposing unrealistic expectations on frontline workers and then simply blaming them when they fail to cope. Today, the UK Health and Safety Executive puts the following statement at the heart of its approach:

“Human failure is normal and predictable. It can be identified and managed.”

That is why modern ‘human errors’ are often quite different from what we instinctively imagine them to be. They are no longer solely operator errors. They can be failures to recognise a flaw in the system design that leaves a task beyond the operator’s reasonable capabilities. They can be failures of management to anticipate honest mistakes and mitigate their consequences. They can be failures by executives to keep up with modern working practices and adopt them within their organisations.

None of this means that the operator is now implicitly cleared of all responsibility. Negligence, lack of focus and deliberate violations of rules cannot—and should not—be tolerated. But the operator no longer carries the entire burden of responsibility for an accident and the damage it causes. They remain accountable within the scope of their responsibilities, their abilities, and the balance between the two.

Responsibility for deficiencies in that balance—and for a system’s inability to protect itself against annoying but entirely predictable human slip-ups—belongs to the system and to the people who designed, organised and managed it.

And that is, without doubt, a good thing.

Security ain’t simple, and it will never be

Every few months or so, we get a message from a customer that sounds like this:

I am looking to integrate JWT to my app. I found this tutorial and trying to follow it in my code. I am now trying to encrypt the signature with an RSA public key and decrypt it later with my private key to compare the hashes, but for some reasons my encryption results are always different.

If you don’t follow what’s happening, and I think most of my readers don’t, here’s what.

First, one guy publishes a tutorial that explains the townsfolk a general process of building a space rocket. Just take some titanium for the body, solder a guidance system (shouldn’t be that much harder than soldering that SatNav chip to your Arduino board), get some rocket fuel – just be careful, it is a bit super-deadly – and in a few months top you’ll be able to check for yourself whether the Great Wall can really be seen from space.

This makes Mick, an honest town lad, interested (he was a bit into rockets himself back in Y7), and he decides to launch a space travel business, using that tutorial as a guide for building his own space rocket. Mick decides to replace titanium with aluminum (as that is cheaper that way), but his aluminum doesn’t stay in shape as per the instructions because the feathering is too heavy for it. He feels frustrated and decides to get rid of some of the feathering.

Meanwhile, the town is getting interested in the project, and Mick’s bookings are growing steadily.

* * *

When my friend got her first car, her mum said to her: I’m super happy for you, darling. Could you please promise me that you will always bear in mind one important thing: it may not always look like that, but you are about to take care of a 3-tonne killing machine. Please be careful.

My friend recalls these words every time she turns the key.

We need to grow up. We need to understand that security is serious. We need to bear in mind that by integrating security into a product we are taking care, well, not of a killing machine, but of something of a very similar scale. Taking it lightly is extremely dangerous.

And I think Mick is as much of a victim here as his customers are. Tutorials like the one mentioned in the beginning of this post make complex things look simple. They make high-risk systems appear risk-free. They say, ah look at this funny thing here, it is called security and even you can do it. Go ahead!

I have actually been a Mick numerous times myself. I love doing things with my hands and consider myself a capable DIY’er – something of an orange or even green belt. And yet, dozens of times I have let YouTube DIY videos delude myself into thinking that a job is not as complex as I thought it was. Hey, just look how easy it was for that young couple to build a patio. Surely it can’t be that hard?

The outcome? I don’t want to talk about it.

And that’s why I stopped writing any manuals, guidance, todo’s, instructions, or whitepapers on security topics unless I am absolutely certain that the audience is capable of following them. Even when I do, I warn my readers that the job they are looking to embark on requires excellent technical competence, and I do so boldly and unambiguously. Security engineering is one of the largest surfaces for the dropped washers, and by directing irresponsibly you are playing your own part in creating the future chaos.

So, let’s re-iterate it for one last time:


WARNING:

Security is complex and can be dangerous if approached irresponsibly. Please, do not make it look simple.


Picture credit: FDA

The Dropped Washer Effect

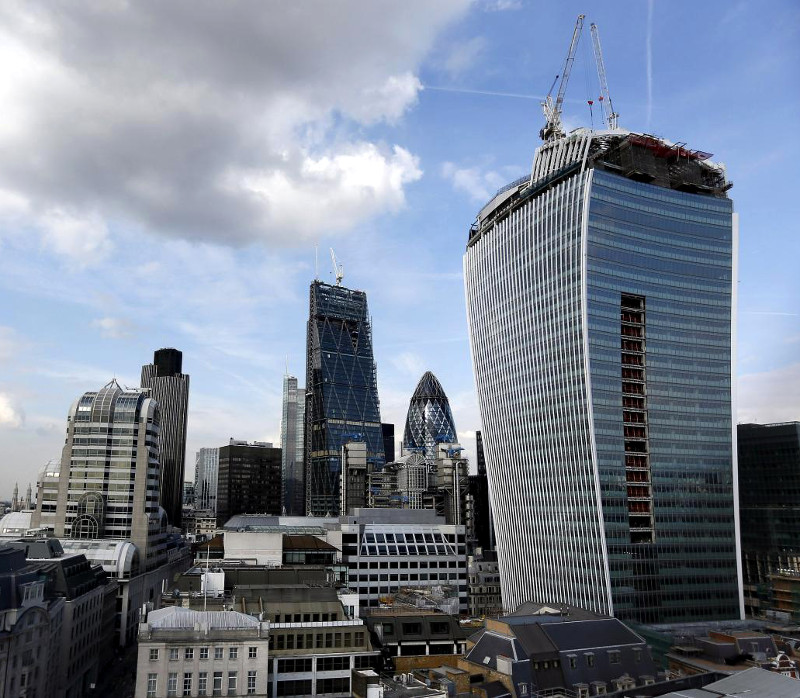
One of these buildings can melt your car down. Can you identify the culprit?

Have you ever come across a situation where something, utterly negligible and minor, had become a cause for a major disruption or even an accident? Such as a small crack in an underground water pipe, dripping inconspicuously for a couple of years, and eventually causing a landslide after accumulating a critical mass of water? Or a seemingly common glass building capable of focusing the sunlight so that it melts the bodywork of cars parked nearby?

If so, chances are high that you observed an example of the Dropped Washer effect. Named after a Boeing 737 accident in Okinawa, Japan, the dropped washer effect describes large-scale adverse events that happened because of the cause of an incomparably lower significance. The unfortunate Boeing ended up burning out completely because of a missing slat mechanism washer, 0.625 inches wide, that the engineering crew forgot to replace after the aircraft’s last service.

One characteristic of the potential dropped-washer features that makes them particularly naughty is their zero perceived value for the business. Offering no added opportunities and presenting no apparent risks for the product, they often do not even exist in the minds of the product stakeholders. This important peculiarity makes it all too easy for them to slip every safety measure employed in modern production flows – from risk assessment to quality control.

Happily, in many cases there are techniques that can help increase our chances of spotting and eliminating the dropped washers from our projects.

Check out my new paper here.

Picture credit: Reuters

Check Your Backups, Now

Last week, a number of services hosted in Google Cloud suffered a dramatic outage. Following a maintenance glitch, services like YouTube, Shopify, Snapchat, and thousands of others became unavailable or very slow to respond. Overall, the services were down for more than four hours, before the availability of the platform was finally restored.

The curious thing about this incident was not the outage itself (sweet happens), but the circumstances behind it that made it last that long. Cloud service providers, as a rule, aim for the highest levels of availability, which are carved in their SLAs. So how could it happen that one of the leading global computing platforms was taken down for more than four hours? Happily, Google is very good in debriefing its failures, so we can have a sneak peek at what have actually happened behind the scenes.

It all started with a few computing nodes which needed to undergo routine maintenance and thus had to be temporarily removed from the cloud – a common day-to-day activity. And then something went wrong. Due to a glitch in the internal task scheduler, many more other, worker nodes had been mistakenly dismissed – drastically reducing the total throughput of the platform, and causing a Chertsey-style gridlock.

Ironically, Google did everything right, exceptionally right. They considered that risk on the design stage. They had a smart recovery mechanism in place that should have kicked in to recover from the glitch and provide the necessary continuity. The problem was that the recovery mechanism itself was supposed to be run by the faulty scheduler. Yet, being a system management task with a lower priority than the affected production services, it was pushed far back in the execution queue. And since the queue was miles long by that time, the recovery service in the choking cloud has never made its way to its time slice.

Any lessons we can learn from this incident? There are myriads; the deeper your knowledge about cloud infrastructures is, the more conclusions you can draw from it. A security architect can draw at least the following two:

1. Backing up systems is a process, not a one-off task. Your backup routine might have worked at the time you set it up, but things break, media dies, and passwords change.  Don’t risk, go and test your backups now – emulate a disaster, pull that cord, and see if your arrangements are capable of providing continuity. Don’t be tempted just to check the scripts – try the actual process in the field. Put this check on your schedule and make it a routine.

2. When designing a backup or recovery system, take extra care to minimize its dependencies on the system being recovered. It is worth remembering that modern digital environments are very complex, and you might need to be quite imaginative to recognise all possible interdependencies. The recovery system should live in its own world, with its own operating environment, connectivity, and power supply.

It is very easy to get caught in this trap, as it gives us the imaginary peace of mind we’re craving for. We know that the system is there for us, and we sleep well at night. We know that should a bad thing happen, it will give us its shoulder. We only realise it is not going to when it’s too late to do anything to make it right.

Just as I was writing this, my friend called me with a story. She went on an overseas trip, and, while being there, wanted to Skype home. Skype, however, having realised her IP was unusual, applied extra security and sent her a verification e-mail. It all would have ended there, if only her Skype account wasn’t bound to a very old e-mail account at an ISP that was blocked in the country for political reasons – so she couldn’t get to her inbox to confirm her identity. Luckily it was just Skype and luckily she knew about VPN – but the things might have become way more complex with a different, life-critical service.

So, really, you will never know how a cow catches a hare. There are way too many factors that may kick in unexpectedly, and, worst of all, unknown unknowns are among them. Still, by using the above two approaches wisely and persistently, you may reduce the risks to the negligible level, which is well worth the effort.

Picture credit: danielcheong1974

A Bag of Contention

A lot has been said about passengers stopping to collect their cabin bags while escaping the blazing Aeroflot aircraft in Moscow last week. Some media went as far as blaming them for excessive deaths of those trapped behind them, with certain Russian politicians even urging to initiate criminal proceedings against those who stopped to pick their bags up (yes, in Russia, party still goes to you © Yakov Smirnoff).

The moral perspective of this complicated matter is unlikely to ever have any kind of satisfactory resolution. It goes deep into the pre-social parts of our brain, mostly cared for by instincts, reflexes, and fight-or-flight responses – and nature is extremely difficult to judge. In the moments of extreme stress and imminent risk of death, few people would think of anything other than their own salvation. The extent of that few depends on many factors, with different social groups balancing fight, flight, and collaborate differently, but it is crystal clear that we can’t blame people for acting selfishly when their lives are in danger.

That being said, there is no doubt that the problem must be dealt with, for the sake of our own future, first of all. Obviously, the collection of cabin bags did delay the evacuation (though the extent of its contribution is yet to be assessed – and I hope it will be assessed). Yet, what’s more important, is that should a similar accident happen again, in whatever town or country it might take place, the behaviour patterns of the escaping passengers are very likely to be highly similar to what we’ve observed in Sheremetyevo.

The fact is, the safety rules around hand luggage, both written and unwritten, are quite relaxed. Effectively, you can do whatever you like with your bags while on board as long as they fit into the airline’s allowance and don’t contain prohibited items. While pre-flight safety briefings advise you against taking your cabin bags with you during evacuation, this is hardly being enforced. It might be hard to resist the temptation to grab the bag that contains valuables such as your passport, phone, or laptop.

One of the reasons for that is that over the last few decades the role and concept of cabin luggage significantly changed – while the rules governing it remained largely the same. For the vast share of today’s passengers, their cabin bags are their primary and only luggage, especially on short-haul flights. It differs drastically from what it used to be twenty years ago, when most of carry-on items were jackets, overcoats, clutches, and an odd duty free bag, with the principal luggage checked into the aircraft hold. The hold itself acted as a physical security control: in case of an emergency, there was no way for the passengers to retrieve their bags. The small or useless carry-on items didn’t pose any risk of a slowdown during the evacuation. Conversely, most of hand luggage items today are stuffed-to-capacity purpose-made ‘cabin bags’, designed and manufactured specifically to ‘just fit’ into the measuring cages. This makes a huge difference, and this is the problem that must be addressed in the safety rules.

The abundance of bulky personal items on board the aircraft is even more complicated by the fact that with many airlines you can’t bring two cabin bags on board, however small the second one is. This forces you to fit everything you need to take with you into that single piece, mixing items of low and high value in one huge cabin suitcase. Should you need to evacuate, even if you would only intend to grab the high-value items, you would have no other option but to take the bulky low-value ones with you too.

So we need to find a convenient way to address those matters. We can’t make people not care about what they value (e.g. their passport) – but we can totally help them with leaving whatever they value less behind. For example, we could give the cabin crew the powers to lock the overhead cabin bag compartments for the whole duration of the flight, and at the same time extend the hand luggage policy to include a [much] smaller second bag. This second bag could be as small as a clutch, a belt bag, or a neck pouch – just enough to accommodate your passport, phone, and wallet.

Such approach would let passengers separate their items of importance (which in most cases are quite compact in size) from the less significant ones. It would introduce a security control in the form of a lockable overhead compartment, yet give passengers peace of mind that the items they value won’t be lost or destroyed should they need to evacuate.

One way or another, one thing that can be said for sure is that the question of aircraft evacuation and the role of hand luggage in it should not be shelved. The lessons of the Aeroflot crash should be learned, in particular in respect of hand luggage policies and procedures. We would be complete fools if we fail to admit the obvious and simply transfer the blame onto the survivors – since this would mean transferring the punishment onto our future selves.

Facepalm

Facebook, ever again, shows that it prefers to learn on its own mistakes rather than someone else’s. This time, it’s about storing passwords in plain text: a textbook security negligence, at different times stepped on by Equifax, Adobe, and Sony.

And this really doesn’t help in building confidence in the social network. We entrust them our most personal pieces of information, and they don’t give a damn about keeping it safe.

“We have found no evidence to date that anyone internally abused or improperly accessed them.”, said Pedro Canahuati, Facebook’s vice president of engineering, security, and privacy. Given all the recent breaches in this company’s security, I can’t help translating this to human language as “we didn’t bother so we didn’t put any access control audit mechanisms in place, so whoever saw your passwords, there is no (and can’t be) any real evidence to that.”

Just a couple of days ago I was asked to send money via Facebook payment service. In the middle of the payment process I realized it is not possible to make the payment – which would have been a one-off one for me – without having Facebook remember either my card or Paypal details. I stopped, closed the Facebook tab, and paid with a different method. Glad I did.

Picture credit: Alex E. Proimos

The Greatest Backdoor

The greatest backdoor of all times might be running right before your eyes.

Earlier today we were quite surprised to discover that our Windows build server rebooted after installing another set of automatic updates. This looked weird, as automated reboots without an administrator’s approval have never been on our security policy. Still, given that we have just upgraded our Windows Server from 2012 to 2016, we believed it to be a misconfiguration issue and embarked on correcting it.

Surprisingly, disabling automated restarts in Windows Server 2016 appeared to be not an easy task. Believe it or not, but unlike it used to be in Server 2012, there is no direct setting in Server 2016 to disable the reboots. You have to employ awkward workarounds, like always having someone logged in, to stop your server from rebooting. Otherwise, it will always reboot automatically, every time a yet another bunch of updates are downloaded and installed.

This looks very worrying. Many server administrators quite reasonably prefer to be in control of reboots of their servers to harmonise them with their working hours, system load, backup and maintenance schedules, and myriad other factors. A mission-critical server that reboots out of the blue in the middle of the night may (and will) lead to all sorts of problems – from a local DoS after failing to complete the restart, to a gaping hole in the company’s network if a third-party IPS fails to co-operate with the updated version of some Windows component.

From a more distant perspective, by removing the possibility to disable automated reboots, Microsoft has acquired a gigantic ‘power switch’, which it can use to force thousands of servers across the world into rebooting by simply sending them a specific ‘update’ package. This puts the owners of those servers into an uncomfortable position of hostages. Even if we do believe in good intentions of the Seattle company, how can we be sure that someone won’t break into their update delivery environment one day, and use the legitimate update procedure to send to all the Windows servers out there a deadly restart command?

Image credit: pngtree.com

Undeniably smarter: a few more words on smart contracts

I believe a couple of statements from my last post need some clarifications, the most important being that it is most certainly too early for lawyers to start looking for new qualifications – if ever at all.

Self-enforcing contracts can’t replace human lawyers, and won’t do so in foreseeable future. There will always be a place for a well-drafted written contract, just as there will always be a place for professionals knowing how to compose it.

There are no contradictions here. Self-enforcing contracts have a very specific application area. They are perfectly suited for defining and enforcing relationships where the parties are subject to well-defined obligations, which can be formalized and verified in mathematical or logical way. Particular examples of those are cryptocurrencies, stock exchange, automated tellers and vending machines, and various kinds of automated non-repudiation and proof-of-identity check mechanisms. And yes, you will still need a lawyer for anything harder than that. Both traditional and self-enforcing contracts will therefore find their own place under the sun.

Even more, the evolution of self-enforcing contracts will give rise to a new legal specialty of a self-enforcing contract professional. This function will need to possess and combine typical skills of a lawyer with those of a mathematician/cryptographer, to be able to produce robust and provably secure self-enforcing contracts.

These changes, in fact, are no different to changes we are observing in nearly any other area being transformed by the computer-led innovation – let’s leave the creative stuff for us humans, and let the computer do the routine.

Picture credit: openclipart

Undeniably smart: a word on self-executing contracts

One of the core and most fantastic features of blockchain infrastructures is the notion of smart contracts, also called self-executing contracts. This is what makes cryptocurrencies secure. Put simply, smart contracts do not need enforcement, or, in other words, they enforce themselves – exclusively due to the way they are drafted.

Every time that you use a cash machine, you are entering a contract with your bank. Your obligations are to provide a card and a pin. The bank’s obligations are to check the pin and give you money.

This contract has a number of enforcement flaws. You can use a stolen card. The ATM might have been skimmed. Or it can just eat your card, leaving you with no card and no cash. The bank’s software could be buggy and take more money from your account than it gave to you. In other words, there exist a number of situations where you or your bank may fail to fulfill its part of the contract, with the violation needed to be escalated to authorities outside the contract (e.g. a bank teller or the police force).

Smart contracts are not threatened by flaws like this. They just work, by their design. In Bitcoin, there is no way to forge a transaction, or to fool someone into the content of your wallet, because the environment provides a secure way to verify every single transaction via a so-called distributed ledger, which works in a mathematically proven way.

While commonly associated with blockchain technologies, smart contracts may actually come in a variety of forms and shapes. Most of Internet security protocols rely on them in one way or another. For example, Diffie-Hellman key exchange algorithm is a typical smart contract, even though the term itself was introduced much later than the algorithm. You can’t obtain the shared key without following the contract. If you violate the protocol, you’ll end up with a wrong key, so the need to get the correct key enforces you to implement and perform the protocol correctly.

Ironically, (or logically) Internet protocols suck heavily in the functions not covered by the self-enforcing logic. This is particularly annoying for protocols which are supposed to provide communication security. I think I won’t be mistaken if I say that a weakly implemented certificate validation routine in SSL/TLS is the weakest point of a huge number of the protocol deployments, having a potential of bringing in much bigger troubles than BEAST, POODLE and Heartbleed combined. Many, many times I watched developers neglecting this important compound of the protocol, by either bypassing the certificate validation entirely, or using simplified routines not providing adequate protection. Many times I pointed that out to them, and very few bothered to do anything to fix it.

This flaw continues into TLS 1.3*, with the certificate validation compound keeping its role as a standalone external module with the only purpose to tell ’yes’ or ‘no’ to the main protocol implementation when asked. Needless to say, it is very tempting to implement this module as a hard-coded ‘yes’ to avoid bothering with the validation altogether and have the project up-and-running right here, right now, especially if you are under time and budget pressure.

Designing the certificate validation routine into the protocol in the form of a self-enforcing contract would have done a great job in increasing its security. There would be no way for TLS implementers to cheat by avoiding the validation procedure or implementing it in a wrong/simplified way. The validation module would either work right, or cause the whole secure negotiation to fail.

To be fair, this is easier said than done. Designing a robust self-executing contract requires a deep knowledge of maths and formal logic, as well as cryptography. Decent level of knowledge of the application area of the contract is also quite essential. Ultimately, a proper self-executing contract is a high-grade cryptographic algorithm, and as such is subject to all the relevant strength implications. A good smart contract should be capable of proving its correctness and cryptographic strength formally, which is a good piece of challenge for inventors.

Still, despite the challenges, self-enforcing contracts are set to take a major part in our society. They do a great job by removing the whole surface for wrongdoing, fraud, and human error, and bringing in simplicity and convenience – and this is something that a lot of our typical everyday scenarios need.

Just to make you sure that the next generation ATM never eats your card.

(*) Strictly speaking, this is not a flaw of TLS as a protocol (as the standard thoughtfully transfers all responsibility for handling certificate validation properly to the implementers), but this fact doesn’t make TLS environments any more secure.

Picture credit: Pixabay